Custom Inference In Kochi, Kerala
Custom AI inference services in Kochi that optimise how your models run, handling high-volume requests with lower latency and cost.
15
Years of experience
5.0
Google Rating
98%
Client Satisfaction

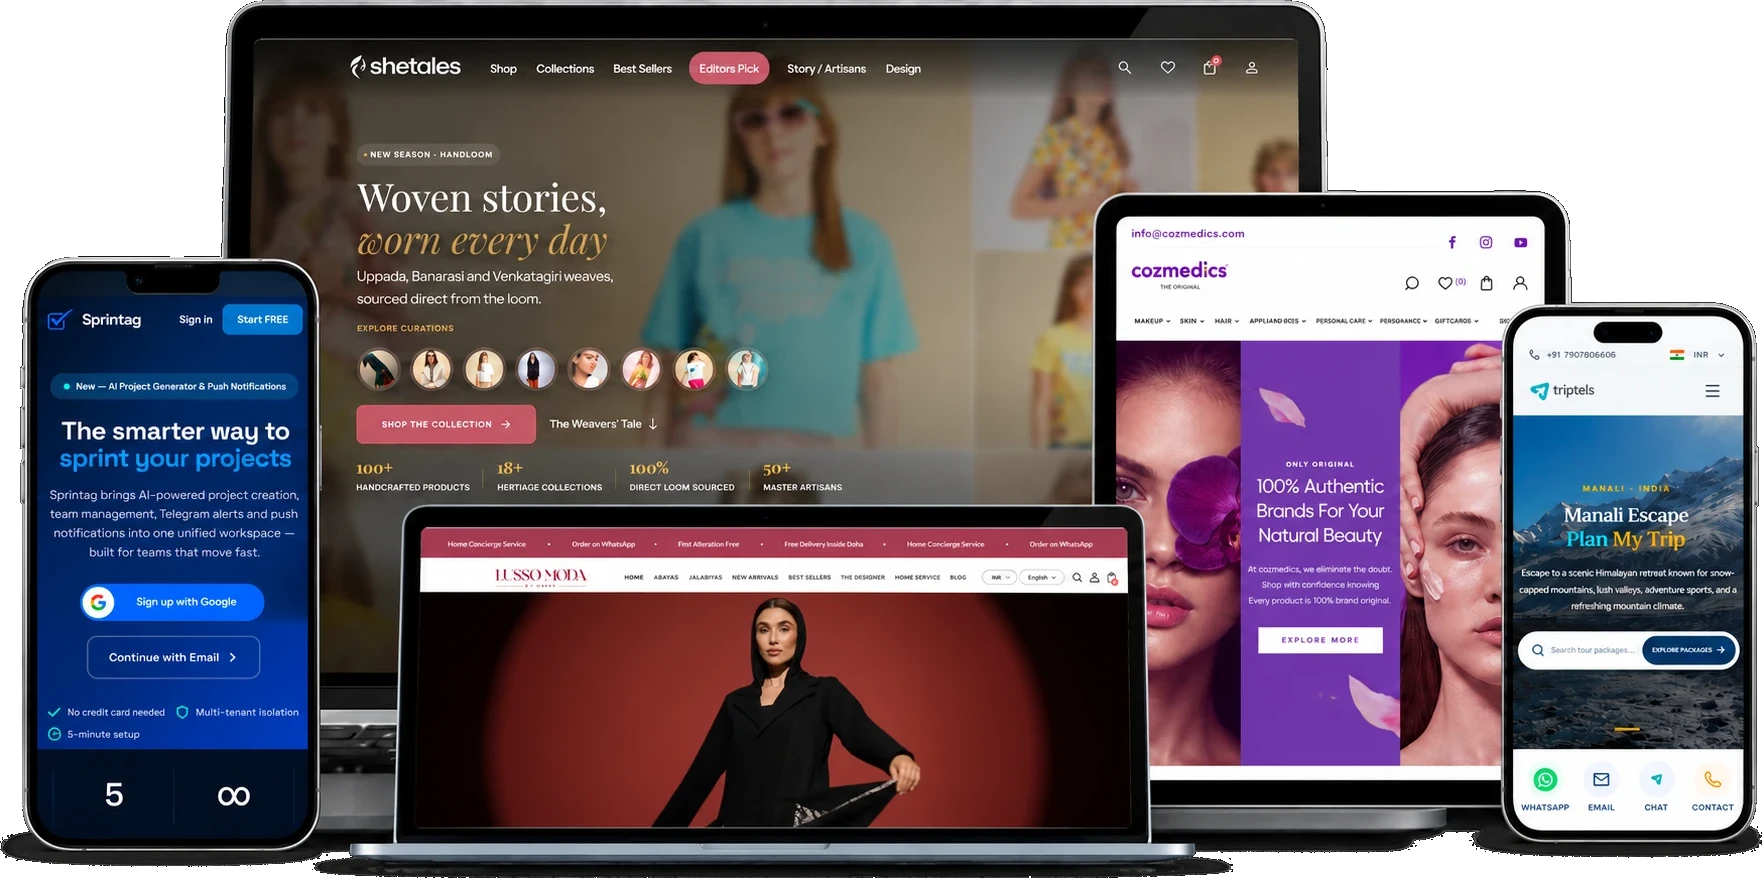
Zilpin – Brass & Bronze Handicrafts E-commerce
Zilpin

ArthaCS – CS & CMA Coaching Institute
Arthacs

Total Associates – Branded Wallpaper Dealer
Total Associates
Zilpin – Brass & Bronze Handicrafts E-commerce
Zilpin
ArthaCS – CS & CMA Coaching Institute
Arthacs
Total Associates – Branded Wallpaper Dealer
Total Associates
Your Custom Inference Partner
01
Optimized Model Architecture
We design robust inference pipelines that utilize model quantization and pruning to ensure your AI runs at peak performance on any hardware configuration.
02
Low-Latency Execution
Our custom inference engines are tuned to minimize response times, allowing your AI agents to interact with UI elements and process data with human-like speed.
03
Certified Infrastructure Expertise
Our experienced AI engineers in Kochi ensure best practices across GPU orchestration, load balancing, and secure deployment for mission-critical applications.
04
Cost-Effective Scalability
We deliver high-value inference solutions that optimize resource consumption, helping you maximize ROI by reducing expensive cloud compute overhead.
Our Custom Inference Process
Discovery & Requirements
We understand your business goals, target audience, and technical requirements.
Planning & Strategy
We define the scope, timeline, and technical approach for the project.
Design & Development
Our team designs and builds the solution using best practices and modern tools.
Testing & Quality Assurance
We thoroughly test for functionality, performance, and reliability before launch.
Launch & Deployment
We deploy the solution and ensure a smooth go-live.
Ongoing Support & Optimization
We provide continued support, monitoring, and improvements after launch.
Related Services
Frequently Asked Questions
001.Can models be fine-tuned on private business data?
002.Do you provide ongoing maintenance and optimization?
003.How is data security ensured during inference?
004.Which models can you deploy from Hugging Face?
005.Is custom inference scalable for enterprise use?
006.What is custom LLM inference?
Ready to Start Your Project?
Tell us what you need and we'll come back with a clear plan and a free quote.